PDF Chatbot
 Sharvari Gohane
Build a complete production-style PDF Chatbot using Python, Streamlit, LangChain, Google Gemini API, and FAISS. Requirements: Allow users to upload multiple PDF files. Extract text from PDFs. Split documents into chunks. Generate embeddings and store them in FAISS. Implement Retrieval-Augmented Generation (RAG). Use Gemini API to answer questions based only on the uploaded PDFs. Show source text chunks used for the answer. Create a clean and modern Streamlit UI. Include error handling and loading indicators. Generate a requirements.txt file. Generate a README.md with setup instructions. Organize the code into multiple files following best practices. Explain the project architecture.


Comments (0)
Sign in to leave a comment
Code Organization
Explore the PDF Chatbot codebase — modular, well-structured, and built for extensibility.
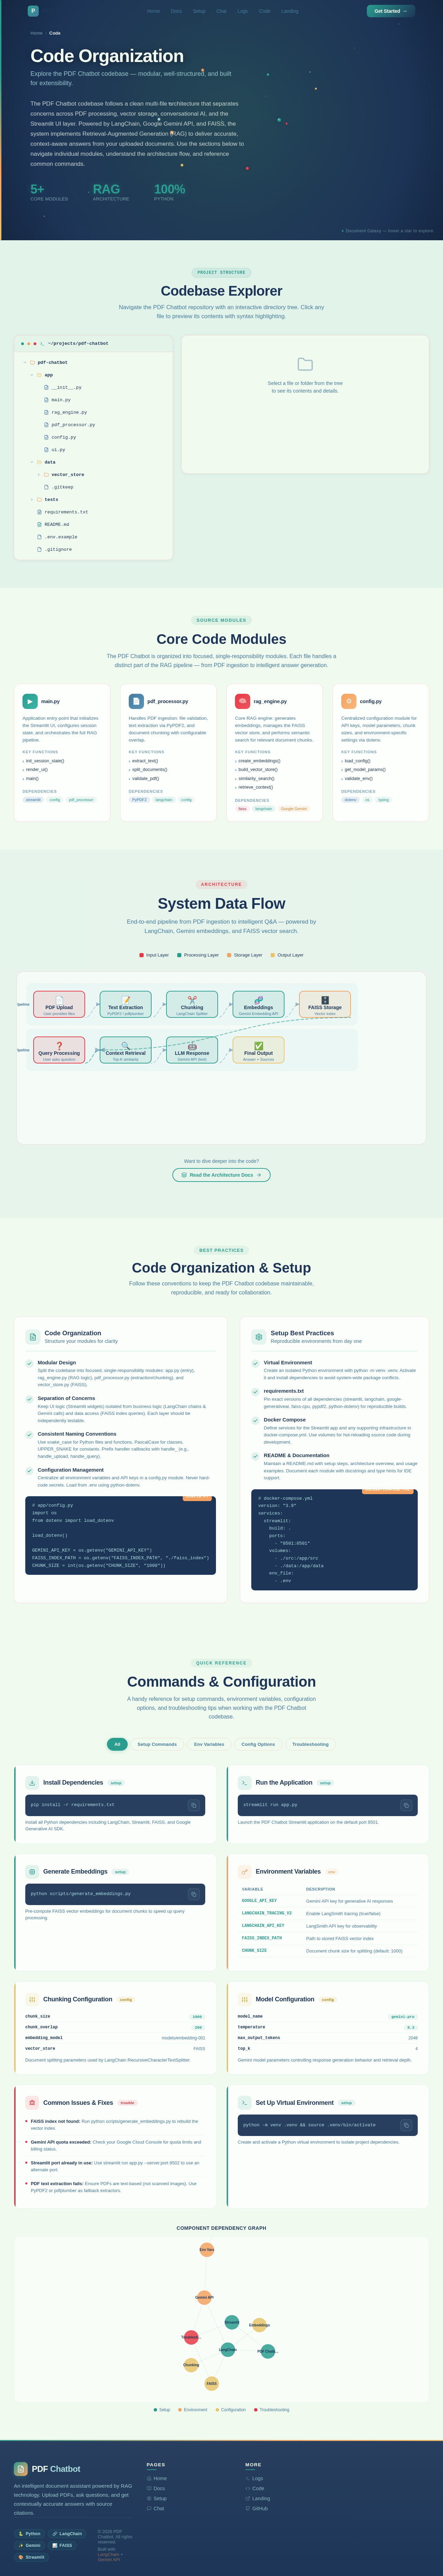
The PDF Chatbot codebase follows a clean multi-file architecture that separates concerns across PDF processing, vector storage, conversational AI, and the Streamlit UI layer. Powered by LangChain, Google Gemini API, and FAISS, the system implements Retrieval-Augmented Generation (RAG) to deliver accurate, context-aware answers from your uploaded documents. Use the sections below to navigate individual modules, understand the architecture flow, and reference common commands.
Codebase Explorer
Navigate the PDF Chatbot repository with an interactive directory tree. Click any file to preview its contents with syntax highlighting.
Select a file or folder from the tree
to see its contents and details.
Core Code Modules
The PDF Chatbot is organized into focused, single-responsibility modules. Each file handles a distinct part of the RAG pipeline — from PDF ingestion to intelligent answer generation.
Application entry point that initializes the Streamlit UI, configures session state, and orchestrates the full RAG pipeline.
- ›init_session_state()
- ›render_ui()
- ›main()
- streamlit
- config
- pdf_processor
Handles PDF ingestion: file validation, text extraction via PyPDF2, and document chunking with configurable overlap.
- ›extract_text()
- ›split_documents()
- ›validate_pdf()
- PyPDF2
- langchain
- config
Core RAG engine: generates embeddings, manages the FAISS vector store, and performs semantic search for relevant document chunks.
- ›create_embeddings()
- ›build_vector_store()
- ›similarity_search()
- ›retrieve_context()
- faiss
- langchain
- Google Gemini
Centralized configuration module for API keys, model parameters, chunk sizes, and environment-specific settings via dotenv.
- ›load_config()
- ›get_model_params()
- ›validate_env()
- dotenv
- os
- typing
System Data Flow
End-to-end pipeline from PDF ingestion to intelligent Q&A — powered by LangChain, Gemini embeddings, and FAISS vector search.
Want to dive deeper into the code?
Read the Architecture DocsCode Organization & Setup
Follow these conventions to keep the PDF Chatbot codebase maintainable, reproducible, and ready for collaboration.
Code Organization
Structure your modules for clarity
Modular Design
Split the codebase into focused, single-responsibility modules: app.py (entry), rag_engine.py (RAG logic), pdf_processor.py (extraction/chunking), and vector_store.py (FAISS).
Separation of Concerns
Keep UI logic (Streamlit widgets) isolated from business logic (LangChain chains & Gemini calls) and data access (FAISS index queries). Each layer should be independently testable.
Consistent Naming Conventions
Use snake_case for Python files and functions, PascalCase for classes, UPPER_SNAKE for constants. Prefix handler callbacks with handle_ (e.g., handle_upload, handle_query).
Configuration Management
Centralize all environment variables and API keys in a config.py module. Never hard-code secrets. Load from .env using python-dotenv.
# app/config.py
import os
from dotenv import load_dotenv

load_dotenv()

GEMINI_API_KEY = os.getenv("GEMINI_API_KEY")
FAISS_INDEX_PATH = os.getenv("FAISS_INDEX_PATH", "./faiss_index")
CHUNK_SIZE = int(os.getenv("CHUNK_SIZE", "1000"))Setup Best Practices
Reproducible environments from day one
Virtual Environment
Create an isolated Python environment with python -m venv .venv. Activate it and install dependencies to avoid system-wide package conflicts.
requirements.txt
Pin exact versions of all dependencies (streamlit, langchain, google-generativeai, faiss-cpu, pypdf2, python-dotenv) for reproducible builds.
Docker Compose
Define services for the Streamlit app and any supporting infrastructure in docker-compose.yml. Use volumes for hot-reloading source code during development.
README & Documentation
Maintain a README.md with setup steps, architecture overview, and usage examples. Document each module with docstrings and type hints for IDE support.
# docker-compose.yml
version: "3.9"
services:
  streamlit:
    build: .
    ports:
      - "8501:8501"
    volumes:
      - ./src:/app/src
      - ./data:/app/data
    env_file:
- .envCommands & Configuration
A handy reference for setup commands, environment variables, configuration options, and troubleshooting tips when working with the PDF Chatbot codebase.
Install Dependencies
setuppip install -r requirements.txtInstall all Python dependencies including LangChain, Streamlit, FAISS, and Google Generative AI SDK.
Run the Application
setupstreamlit run app.pyLaunch the PDF Chatbot Streamlit application on the default port 8501.
Generate Embeddings
setuppython scripts/generate_embeddings.pyPre-compute FAISS vector embeddings for document chunks to speed up query processing.
Environment Variables
env| Variable | Description |
|---|---|
| GOOGLE_API_KEY | Gemini API key for generative AI responses |
| LANGCHAIN_TRACING_V2 | Enable LangSmith tracing (true/false) |
| LANGCHAIN_API_KEY | LangSmith API key for observability |
| FAISS_INDEX_PATH | Path to stored FAISS vector index |
| CHUNK_SIZE | Document chunk size for splitting (default: 1000) |
Chunking Configuration
configDocument splitting parameters used by LangChain RecursiveCharacterTextSplitter.
Model Configuration
configGemini model parameters controlling response generation behavior and retrieval depth.
Common Issues & Fixes
trouble- FAISS index not found: Run python scripts/generate_embeddings.py to rebuild the vector index.
- Gemini API quota exceeded: Check your Google Cloud Console for quota limits and billing status.
- Streamlit port already in use: Use streamlit run app.py --server.port 8502 to use an alternate port.
- PDF text extraction fails: Ensure PDFs are text-based (not scanned images). Use PyPDF2 or pdfplumber as fallback extractors.
Set Up Virtual Environment
setuppython -m venv .venv && source .venv/bin/activateCreate and activate a Python virtual environment to isolate project dependencies.
Component Dependency Graph
No comments yet. Be the first!