dbaseextractor
 Hello Mcdonald
make an app that can crawl the web and web directory to find and extract email leads on the internet


Comments (0)
Sign in to leave a comment
Crawl history
Your crawls
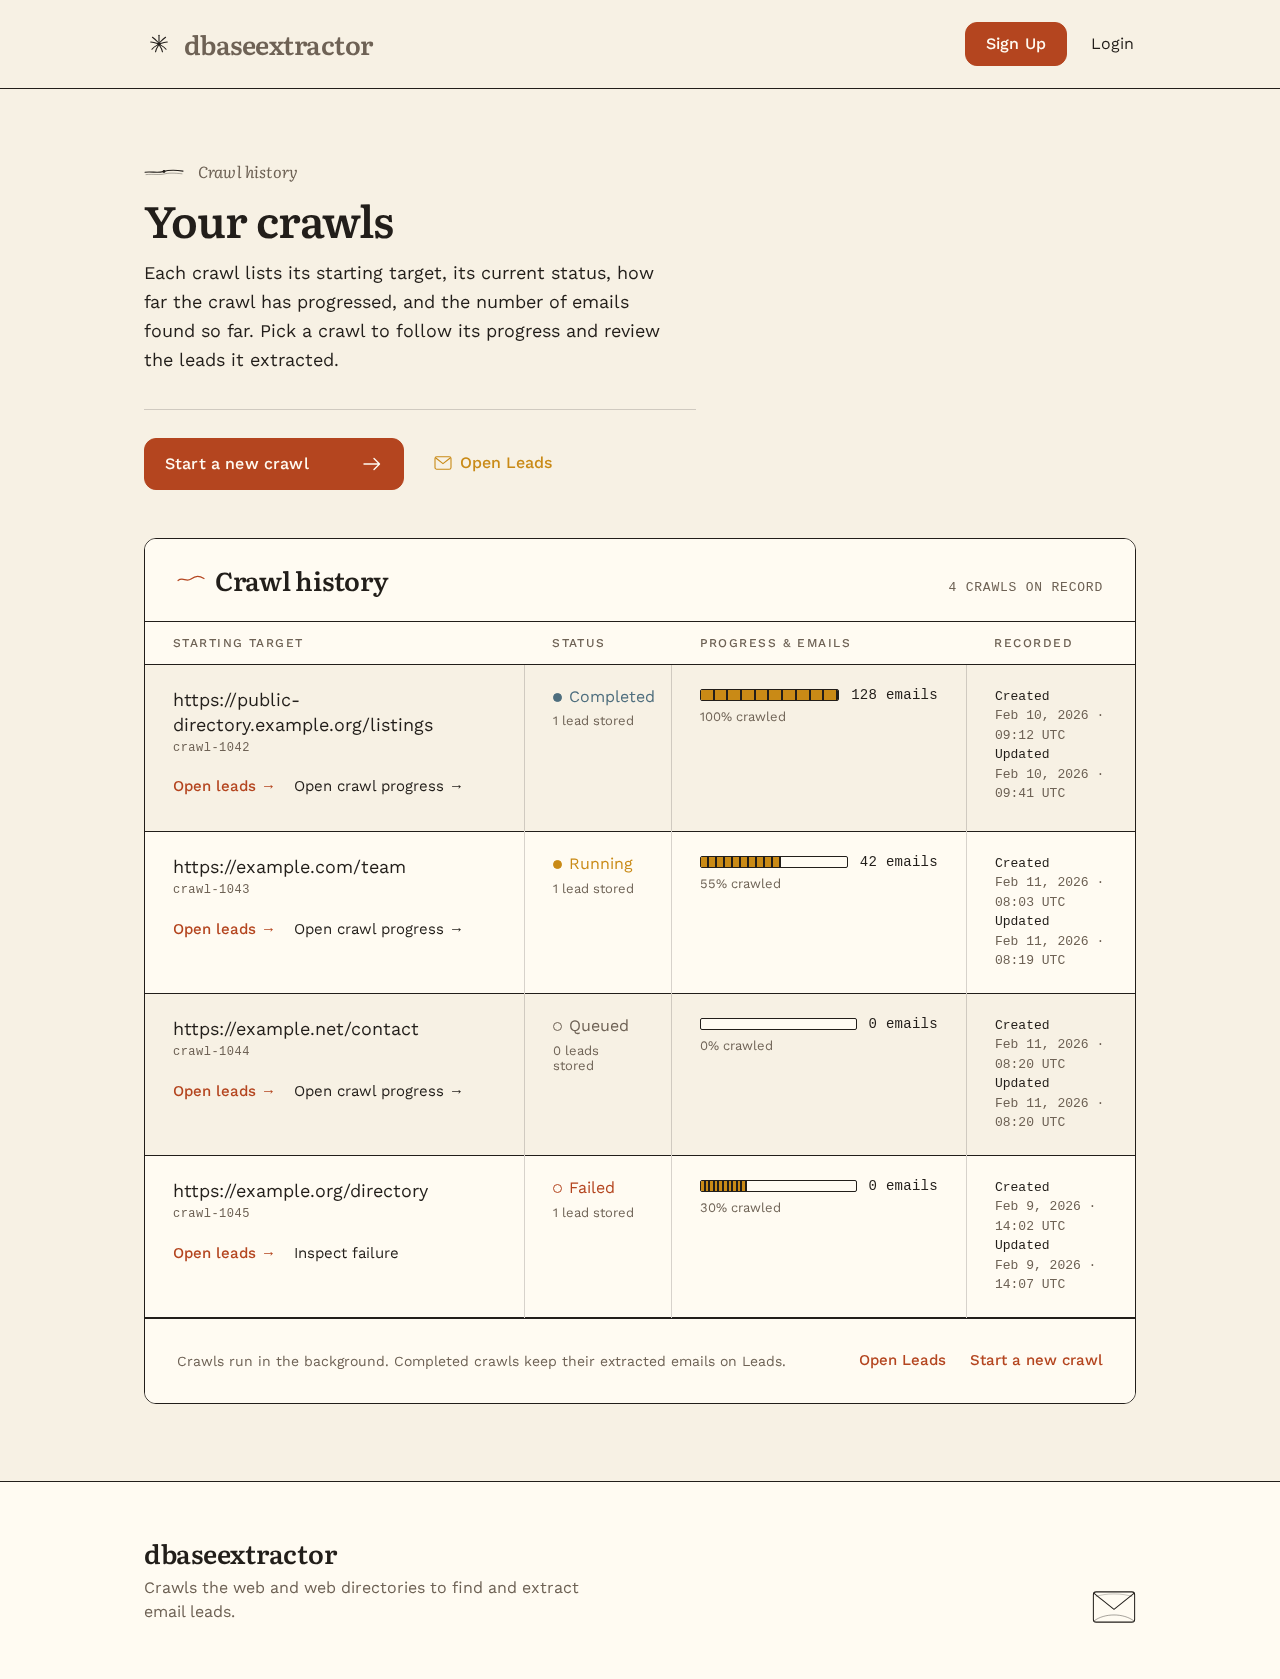
Each crawl lists its starting target, its current status, how far the crawl has progressed, and the number of emails found so far. Pick a crawl to follow its progress and review the leads it extracted.
Crawl history
4 crawls on record
| Starting target | Status | Progress & emails | Recorded |
|---|---|---|---|
| https://public-directory.example.org/listingscrawl-1042 | Completed | CreatedFeb 10, 2026 · 09:12 UTCUpdatedFeb 10, 2026 · 09:41 UTC | |
| https://example.com/teamcrawl-1043 | Running | CreatedFeb 11, 2026 · 08:03 UTCUpdatedFeb 11, 2026 · 08:19 UTC | |
| https://example.net/contactcrawl-1044 | Queued | CreatedFeb 11, 2026 · 08:20 UTCUpdatedFeb 11, 2026 · 08:20 UTC | |
| https://example.org/directorycrawl-1045 | Failed | CreatedFeb 9, 2026 · 14:02 UTCUpdatedFeb 9, 2026 · 14:07 UTC | |
This crawl stopped before finishing. The crawl could not continue from its starting target. Pages it had already reached were skipped over; no further emails were extracted. The record is kept here so you can review where it stopped.
| |||
Crawls run in the background. Completed crawls keep their extracted emails on Leads.
dbaseextractor
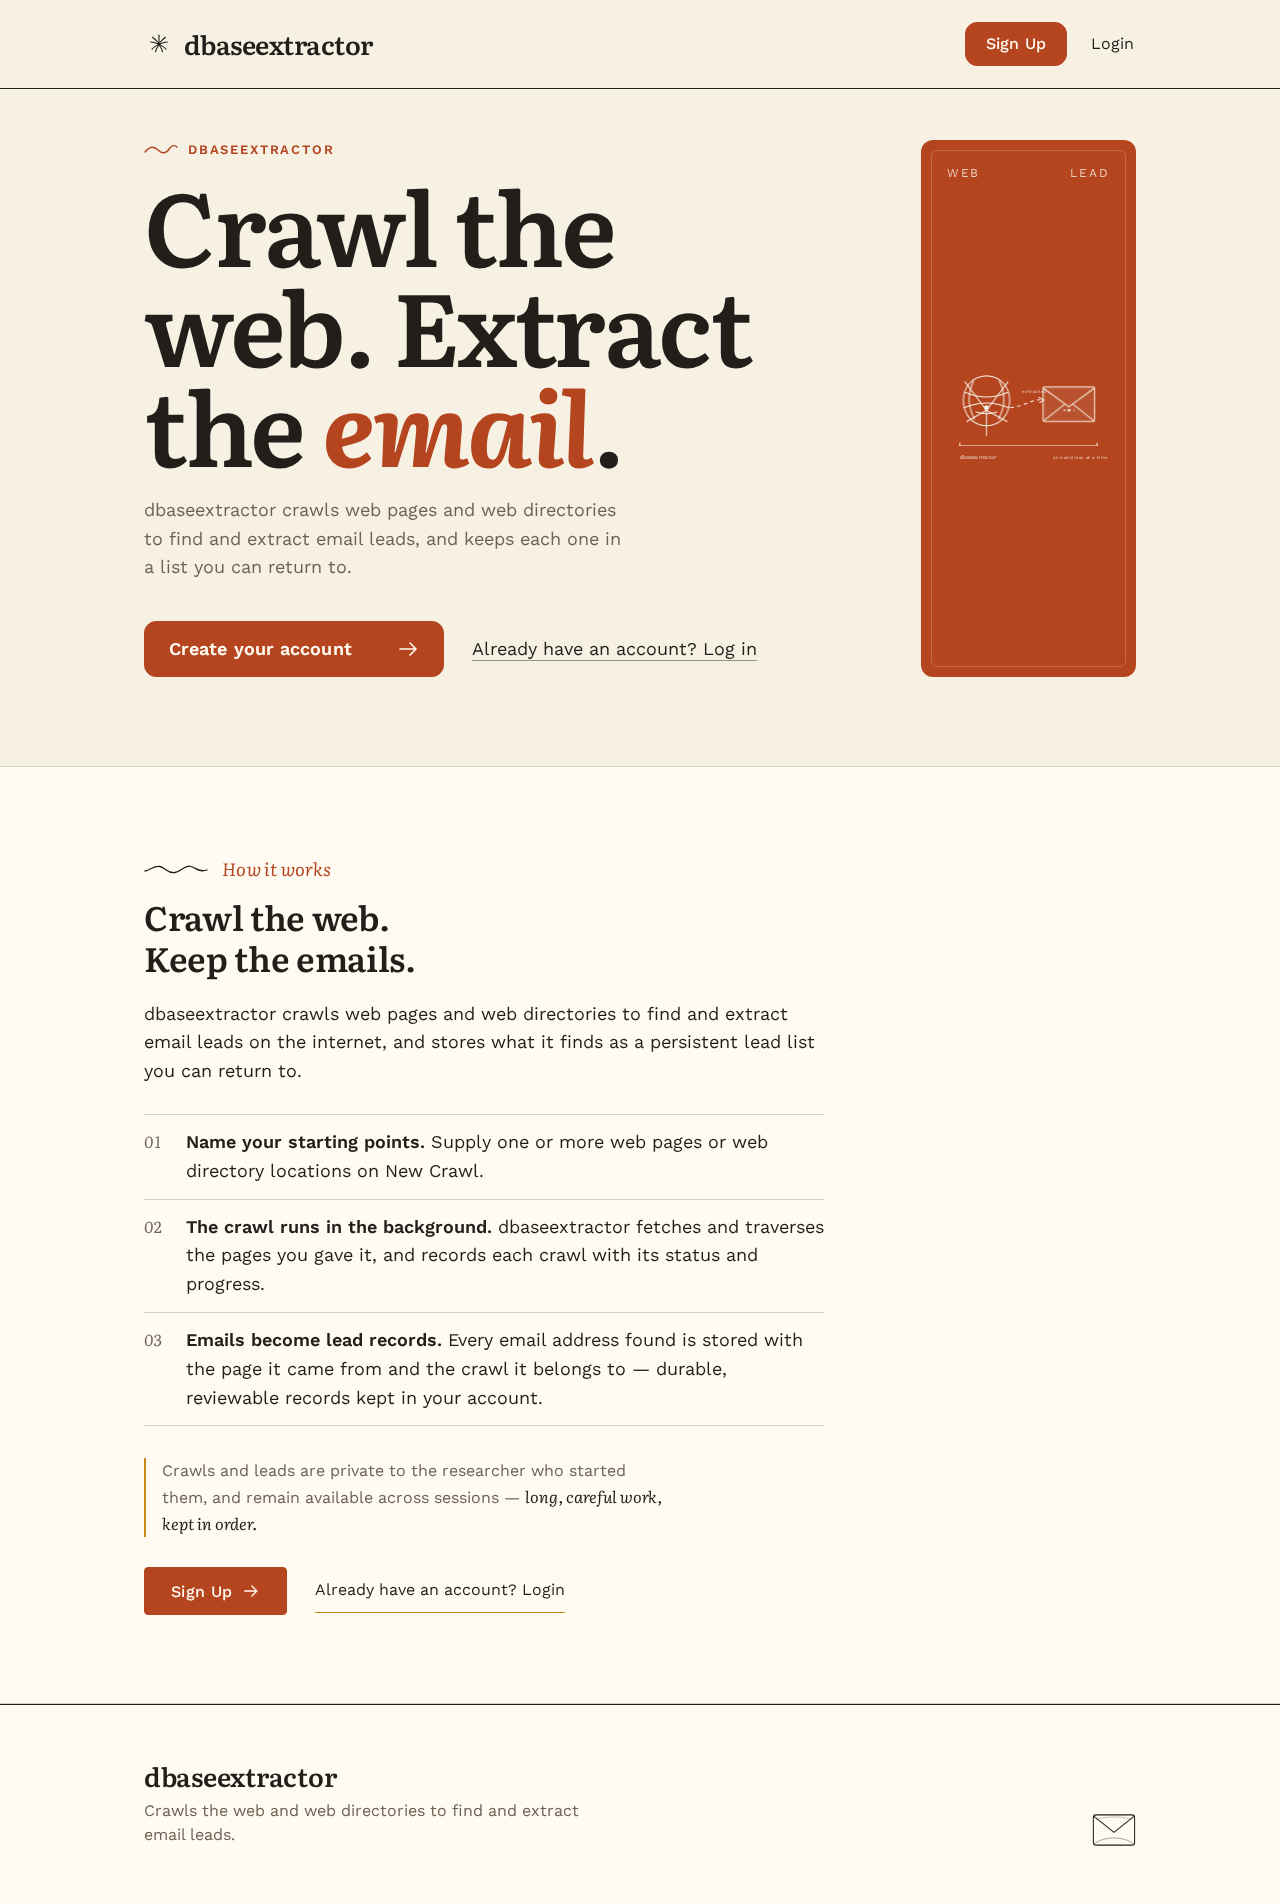
Crawl the web. Extract the email.
dbaseextractor crawls web pages and web directories to find and extract email leads, and keeps each one in a list you can return to.
Crawl the web. Keep the emails.
dbaseextractor crawls web pages and web directories to find and extract email leads on the internet, and stores what it finds as a persistent lead list you can return to.
- Name your starting points. Supply one or more web pages or web directory locations on New Crawl.
- The crawl runs in the background. dbaseextractor fetches and traverses the pages you gave it, and records each crawl with its status and progress.
- Emails become lead records. Every email address found is stored with the page it came from and the crawl it belongs to — durable, reviewable records kept in your account.
Crawls and leads are private to the researcher who started them, and remain available across sessions — long, careful work, kept in order.
No comments yet. Be the first!