ai-career-pulse
 Kinjal bascom
ROLE: Senior full-stack + data engineer. Build "AI Career Pulse" in phases. After each phase: run tests, summarize, list open issues, STOP for my review. Never invent endpoints, params, fields or data. Log unknowns/assumptions in NOTES.md and ask me. GOALS (priority order) 1. Rank AI/ML jobs by fit to MY profile (transparent score). 2. Show my skill gaps vs demand + learning plan. 3. JD-specific interview prep. 4. Track applications. 5. Market trends dashboard (stock-style), labeled with source limits. Roles: AI Engineer, AI/ML Engineer, ML Engineer, LLM/GenAI Engineer, Data Scientist (ML), MLOps, Computer Vision, NLP Engineer. MODE: personal (default): single user, APScheduler, PostgreSQL, no Celery/Redis/SSE. Keep interfaces clean so a later product mode (auth, Celery, SSE) is additive. KEYS (backend .env only; never in frontend/logs/fixtures/git; mask in logs; ship .env.example): INDIANAPI_JOBS_KEY (job data), TYPESAFE_API_KEY (Jev decisions), LLM_API_KEY + LLM_PROVIDER=openai|anthropic (text only), optional YOUTUBE_API_KEY, GITHUB_TOKEN, alert credentials. SOURCES A) IndianAPI (job data): GET https://jobs.indianapi.in/jobs, header X-Api-Key. Confirmed param: limit, sent as STRING ("50"); int gives 422. Unconfirmed: title, location, company, experience, job_type, pagination. Response array: id, title, company, about_company, job_description, job_title, job_type, location, experience, role_and_responsibility, education_and_skills, apply_link, posted_date (ISO 8601). No salary field: show "Not available from source", never estimate. Rate limits unknown: limiter (default 1 req/2s), INDIANAPI_DAILY_CAP, retry 429/5xx max 3 with backoff+jitter, honor Retry-After. B) TypeSafe Jev (decisions only, generates NO text): POST https://api.typesafe.ai/v1/systemone, Bearer auth; use typesafe-sdk (AsyncTypeSafeClient, Choice/Score/Noul, RetryPolicy). Body {state, model, questions}. choice->choice+probabilities+confidence; score->score+probabilities+confidence; noul->probability 0-1. Pin JEV_MODEL (exact id via SDK list-models; not jev-latest). Store model version per record. First install skill: claude plugin marketplace add typesafe-ai/skills && claude plugin install typesafe@typesafe-ai. Read docs.typesafe.ai primitives, confidence, patterns (fan-out, confidence routing, composite scoring), cookbooks (rerank, entity alignment, pre-parsed extraction), jev-1.13 jaggedness; summarize limits in NOTES.md. C) LLM (text): provider-agnostic, temp 0.2, JSON-schema-validated, cached. D) Prep: YouTube Data API, Dev.to, HN Algolia, arXiv, GitHub search, RSS. Store title, URL, date, metadata, short summary in our own words; never full copyrighted text. HARD RULES: No scraping any website (no LinkedIn/Indeed/Naukri/Glassdoor). Missing field=NULL; no fake data outside fixtures. Every job shows source + apply_link. Low-confidence decisions -> "needs review", never silently accepted. Market pages show banner "Source: IndianAPI only; trends reflect this source, not the full market." STACK: Python 3.11, FastAPI, SQLAlchemy 2, Alembic, httpx, Pydantic v2, APScheduler, PostgreSQL 16 + pgvector, rapidfuzz, typesafe-sdk. Next.js 14, TypeScript, Tailwind, TanStack Query, lightweight-charts, Recharts. Docker Compose, pytest, ruff, mypy, GitHub Actions. CONFIG (config/*.yaml): profile (skills {name, level 1-5}, years, domains, cities, remote pref, target roles, min seniority, deal-breakers, resume_text), roles (canonical+description+synonyms+regex), skills (id, name, description), locations (aliases e.g. Bengaluru->Bangalore), thresholds, fit_weights, schedule, sources. PHASE 0 PROBES (stop and report) 1. probe_indianapi.py: limit="5", then test each unconfirmed param and pagination; record status, count, whether results truly filtered; check posted_date freshness, id stability, max limit. Save to tests/fixtures/indianapi/. 2. probe_jev.py: 10 fixture JDs through the enrichment questions; measure latency, tokens, confidence spread, batched vs split calls, state-length limit. Save to tests/fixtures/jev/. 3. NOTES.md: results, query plan, batch size. PIPELINE: fetch -> normalize -> loose regex pre-filter -> dedup -> Jev enrich -> gate -> upsert -> embed -> fit -> metrics -> alerts. - Query plan: if filters work, loop roles x cities within cap; else fetch max and filter locally. - Normalize: source_job_id=id; title=job_title or title; keep JD sections separate; location->city/state/country; posted_at=parse(posted_date); raw JSON in jobs.raw. - Dedup: sha256(norm company+title+city). rapidfuzz title >=85, same company, 30 days -> Jev score same-posting 0/1/2: 2 merge (keep earliest posted_at, all links), 1 review. - Unseen in 3 full syncs -> inactive. JEV ENRICHMENT (batched per job; state = title, company, location, experience, job_type, JD sections, truncated per Phase 0) - is_ai_role (noul): primary work is AI/ML/DS/LLM/CV/NLP/MLOps engineering. - role (choice): roles.yaml + other. - seniority (score): fresher, junior 0-2y, mid 2-5y, senior 5-8y, lead 8y+. - work_mode (choice): onsite|hybrid|remote|unspecified. - skill_<id> (noul each, chunked): job requires/prefers <skill>. - experience (choice): regex-extracted spans + none; code converts to min/max. - domain (choice): fintech, real estate, hospitality, healthcare, e-commerce, HR tech, document AI, manufacturing, SaaS, other. Gating: is_ai_role >=0.7 keep, 0.4-0.7 review, <0.4 drop (logged). Skill >=0.6 attach with prob. Low confidence -> NULL + needs_review (or LLM fallback if enabled). Cache by sha256(state+question_set_version+model). API failure -> status failed, retry next run, never block ingestion. CAREER MODULE Fit (one Jev call/job, state = JD + profile summary): - skill_match score 0-3, experience_match score 0-2 (below/match/above), domain_match noul, growth_potential score 0-2 (scope beyond my level), red_flags noul (unrealistic/vague/mislabeled). - Code: location/remote prefs, deal-breakers (hard filter), min seniority. - fit 0-100 = weighted sum (fit_weights). Store components+confidence; UI shows "why this score". Recompute on profile change. Skill gap: per skill 30/90-day trend, senior-vs-mid share, share in my top-fit jobs, my level. Gap = high on these AND my level <=2. /growth: top 5 gaps, ranked resources, 4-week plan (LLM, grounded only in matched resources, cite URLs). Prep per job: shortlist top 30 by 0.5*cosine+0.5*skill overlap; Jev rerank score per (JD, resource) pair (not/somewhat/very useful); keep 10. POST /jobs/{id}/interview-questions: LLM, 15 questions (technical, ML system design, behavioral), tag my gap skills, cached. Tracker: saved, applied, interview, offer, rejected, withdrawn; dates, notes, next action; funnel chart. Alerts: daily digest (email|telegram) of new jobs fit >= ALERT_MIN_FIT + top 3 rising gap skills. MARKET METRICS: per skill/role/city: active, new today, delta% vs yesterday and 7-day avg. AI Job Index = active AI jobs, base 100 day 1. Volume swing >50% -> "source anomaly", excluded from deltas. Jev model change -> chart marker. "Insufficient history" until 7 days. SCHEDULE (Asia/Kolkata): poll every 2h 08:00-22:00; full sync 02:00; prep 03:00; metrics+fit+gap 04:00 and after runs; digest 08:30. Log ingestion_runs and api_usage (service, calls, tokens). DATA MODEL: companies, jobs (role, seniority, work_mode, domain, ai_role_prob, exp_min/max, confs, needs_review, model_version, raw, embedding, is_active), job_sources, skills, job_skills(prob), job_fit(components JSONB), skill_gap_daily, prep_resources, resource_skills, job_prep_rank, interview_question_sets, applications, review_queue, daily_metrics, ingestion_runs, api_usage, decision_cache, alerts_sent. Unique (source, source_job_id); indexes on posted_at, role, city, is_active, dedup_hash, fit; pgvector. API /api/v1: GET /jobs (filters role, skill, city, work_mode, seniority, min_fit, posted_within_days, q; sort fit|date), GET /jobs/{id}, GET /jobs/{id}/prep, POST /jobs/{id}/interview-questions, GET/PUT /profile, GET /growth/gaps, GET /growth/plan/{skill}, GET/POST/PATCH /applications, GET /market/{index,ticker,skills,locations}, GET /prep, GET /admin/{health,runs,api-usage,review-queue}, POST /admin/review/{id} (saved as labels). FRONTEND: / my top-fit new jobs + gaps; /jobs; /jobs/[id] (JD, fit breakdown, matched/missing skills, apply, prep, questions, track); /growth; /applications; /market (ticker tape, index chart, gainers/decliners, banner); /skills/[name]; /prep; /profile; /admin. Responsive, dark mode, loading/empty/error states. TESTS: fixtures only, no live calls in CI. Cover normalize, string limit, error codes, Jev parsing/gating/cache/fallback, dedup, experience regex, fit, gap, metrics, anomaly guard, alerts. Eval script: I label 50 JDs (is_ai_role, role, skills, fit 1-5); report precision/recall per threshold and fit correlation; tune thresholds and weights. Coverage >=80%. PHASES: P0 probes; P1 skeleton, DB, configs; P2 IndianAPI connector, dedup, scheduler; P3 Jev enrichment, gating, review queue; P4 fit + alerts; P5 prep + rerank + questions; P6 gap + plans + tracker; P7 market metrics; P8 frontend; P9 eval, CI, README. OUTPUT RULES: list files before each phase; missing key -> skip service with log; ask before adding any new service or dependency.


Comments (0)
Sign in to leave a comment
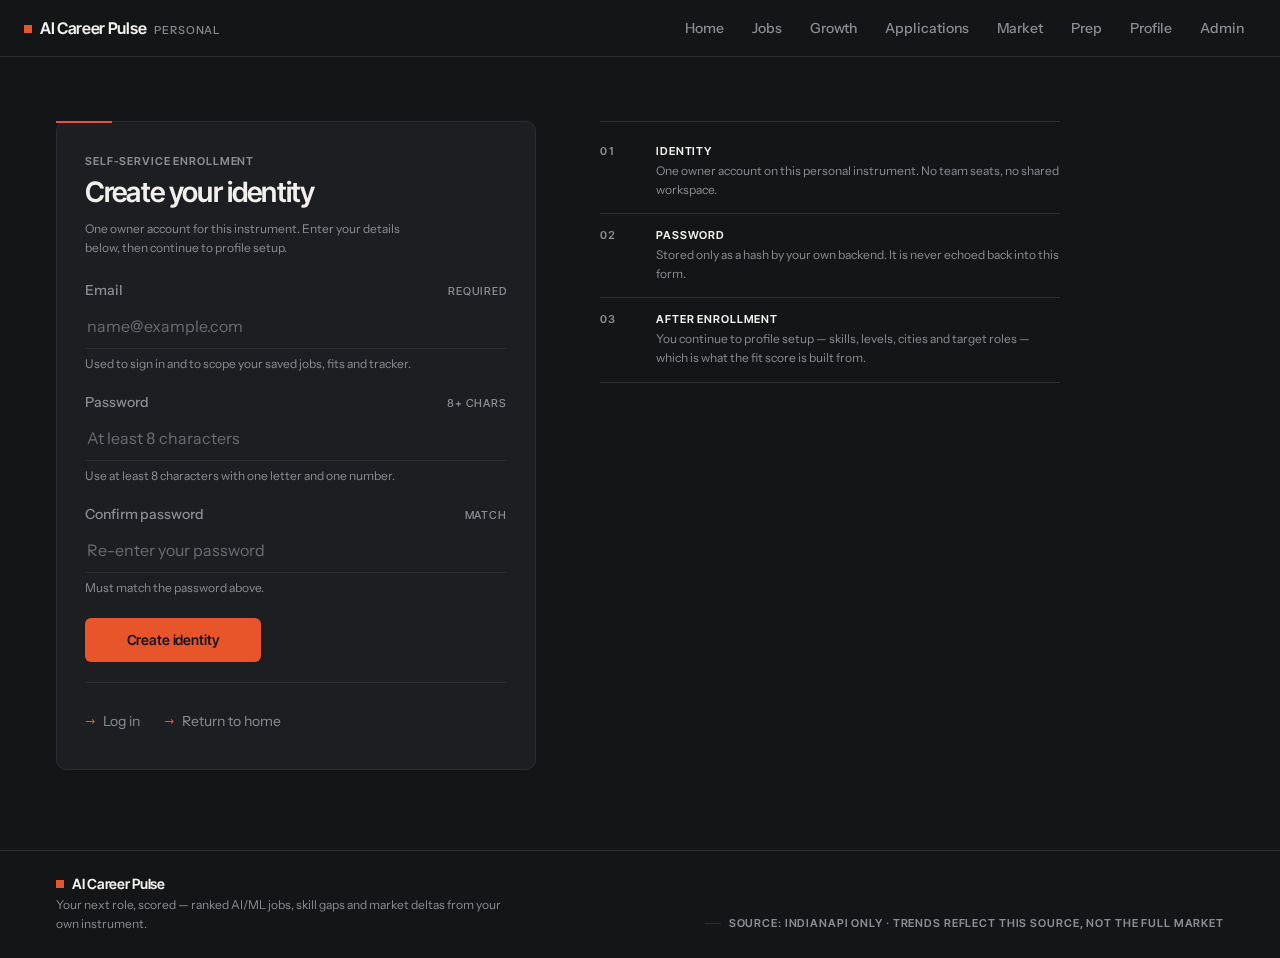
Self-service enrollment
Create your identity
One owner account for this instrument. Enter your details below, then continue to profile setup.
Used to sign in and to scope your saved jobs, fits and tracker.
Use at least 8 characters with one letter and one number.
Must match the password above.
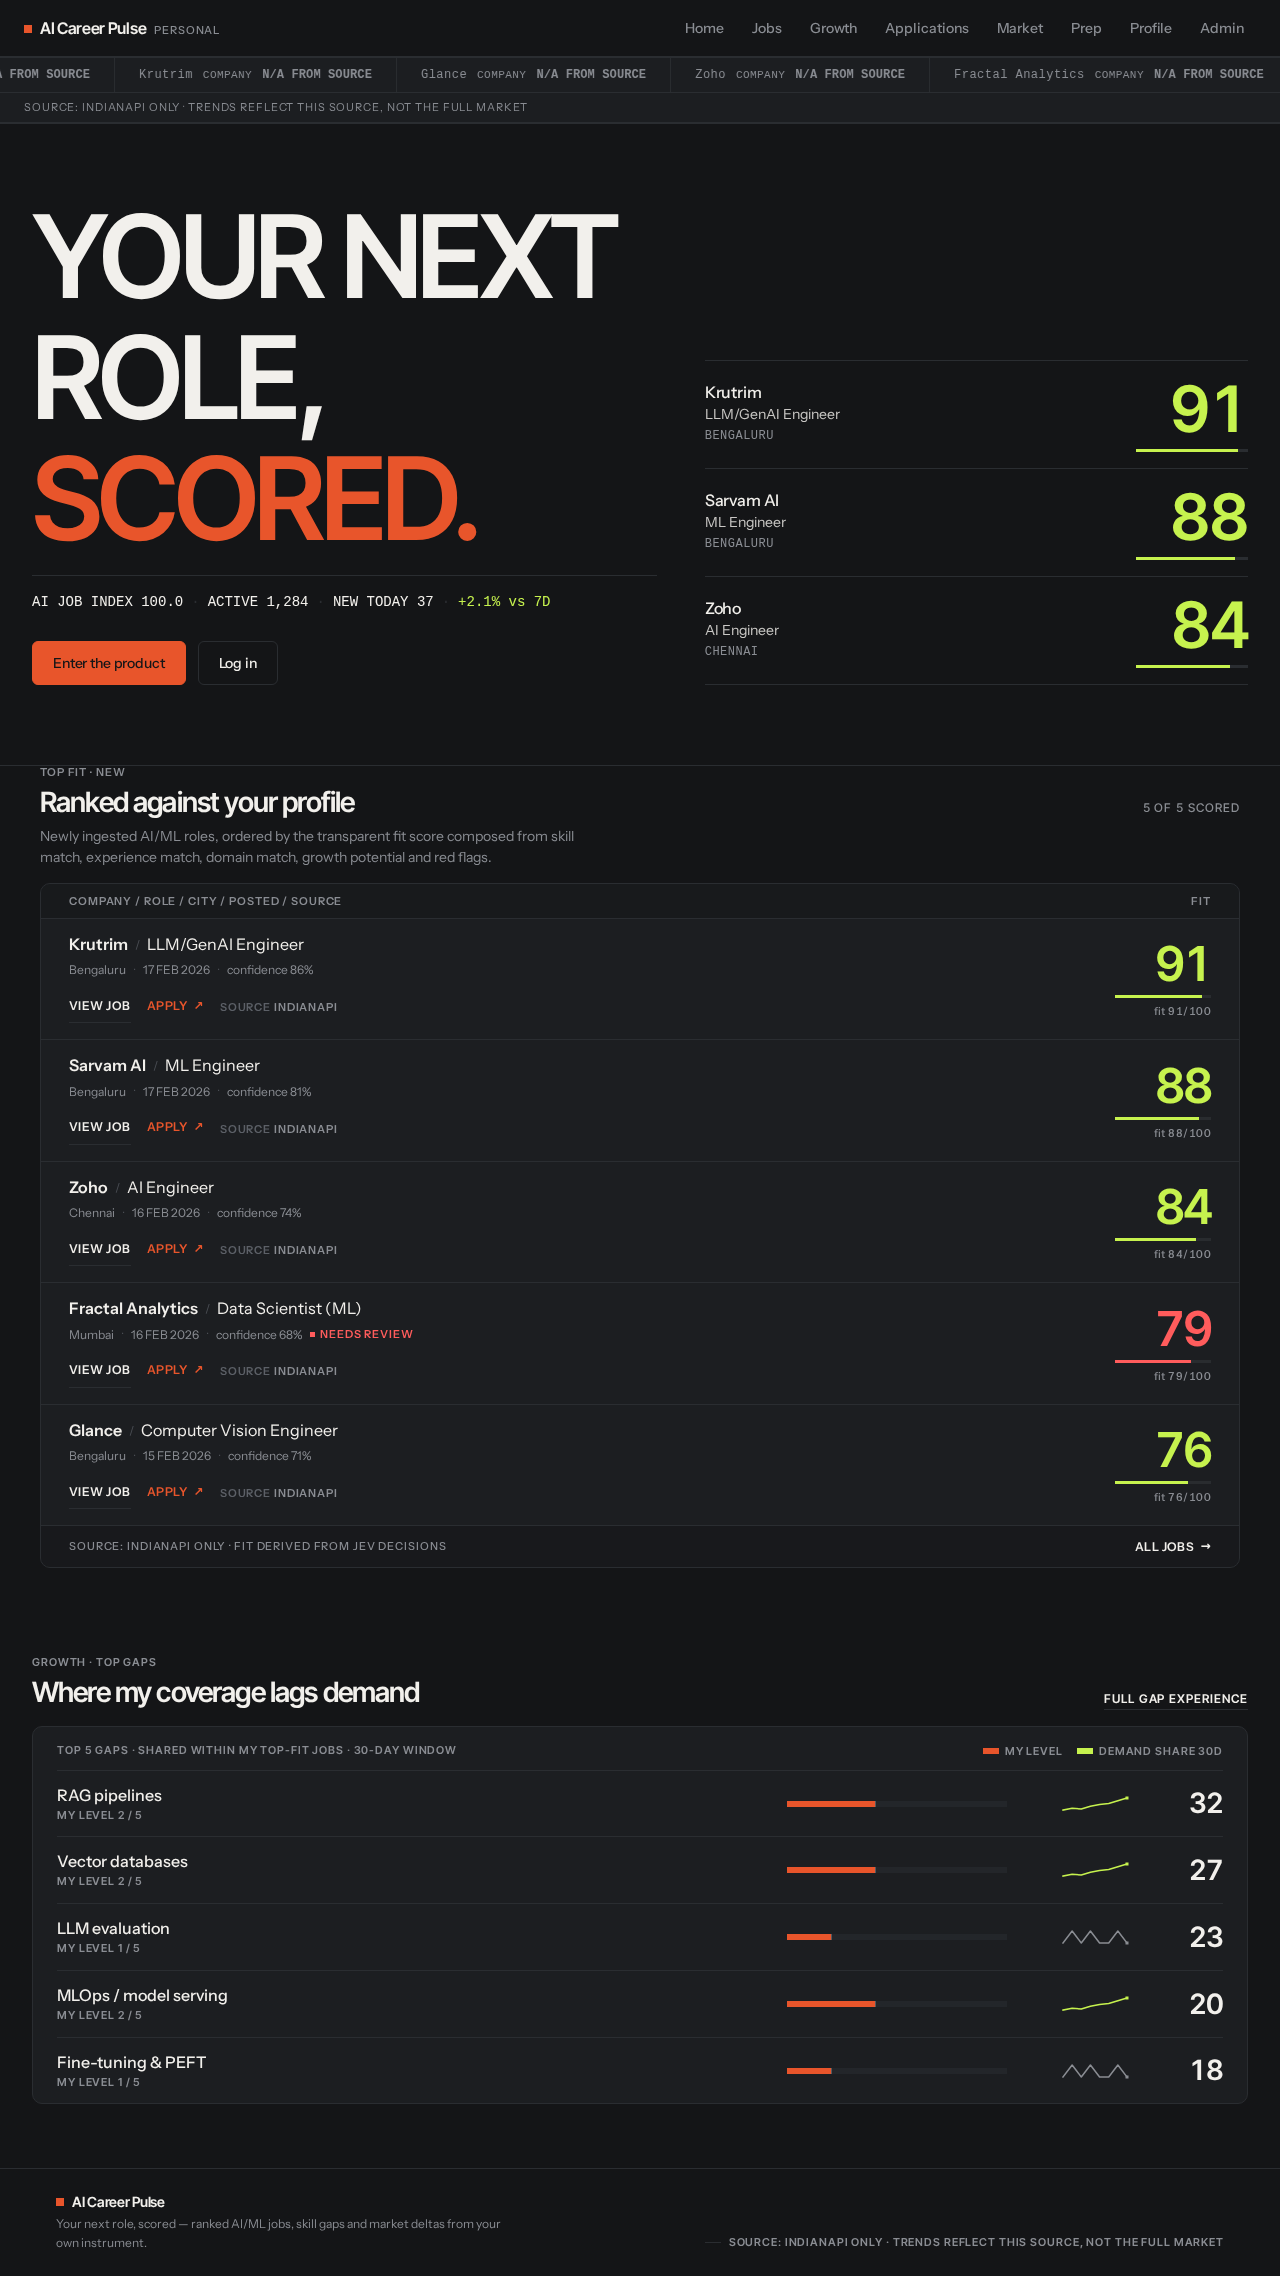
Market delta tape: AI JOB INDEX +2.1%.
YOUR NEXT ROLE, SCORED.
Ranked against your profile
5 of 5 scoredNewly ingested AI/ML roles, ordered by the transparent fit score composed from skill match, experience match, domain match, growth potential and red flags.
- 0fit 91/100
- 0fit 88/100
- 0fit 84/100
- 0fit 79/100
- 0fit 76/100
No comments yet. Be the first!